---
title: "From Magic to Mixed Feelings: Analyzing 'One Hundred Years of Solitude' Reviews"
subtitle: "How readers experience the novel: A deep dive into emotional responses, writing complexity, and thematic connections across different rating categories."
description: "A comprehensive analysis of reader reviews for 'One Hundred Years of Solitude', examining emotional patterns, writing complexity, and common themes through data visualization of Goodreads and LibraryThing reviews."
author: "Steven Ponce"
date: "2025-01-05"
date-modified: last-modified
categories: ["SWDchallenge", "2025"]
tags: [ggplot2, text-analysis, sentiment-analysis, patchwork, tidytext, web-scraping, book-reviews, literary-analysis, Gabriel-García-Márquez]
image: "thumbnails/swd_2025_01.png"
format:
html:
toc: true
toc-depth: 5
code-link: true
code-fold: true
code-tools: true
code-summary: "Show code"
editor_options:
chunk_output_type: inline
execute:
freeze: true
cache: true
error: false
message: false
warning: false
eval: true
# share:
# permalink: "https://stevenponce.netlify.app/data_visualizations/SWD Challenge/2025/swd_2025_01.html"
# description: "Analyzing how readers experience Gabriel García Márquez's masterpiece through sentiment analysis and text mining of online reviews."
# linkedin: true
# twitter: true
# email: true
---
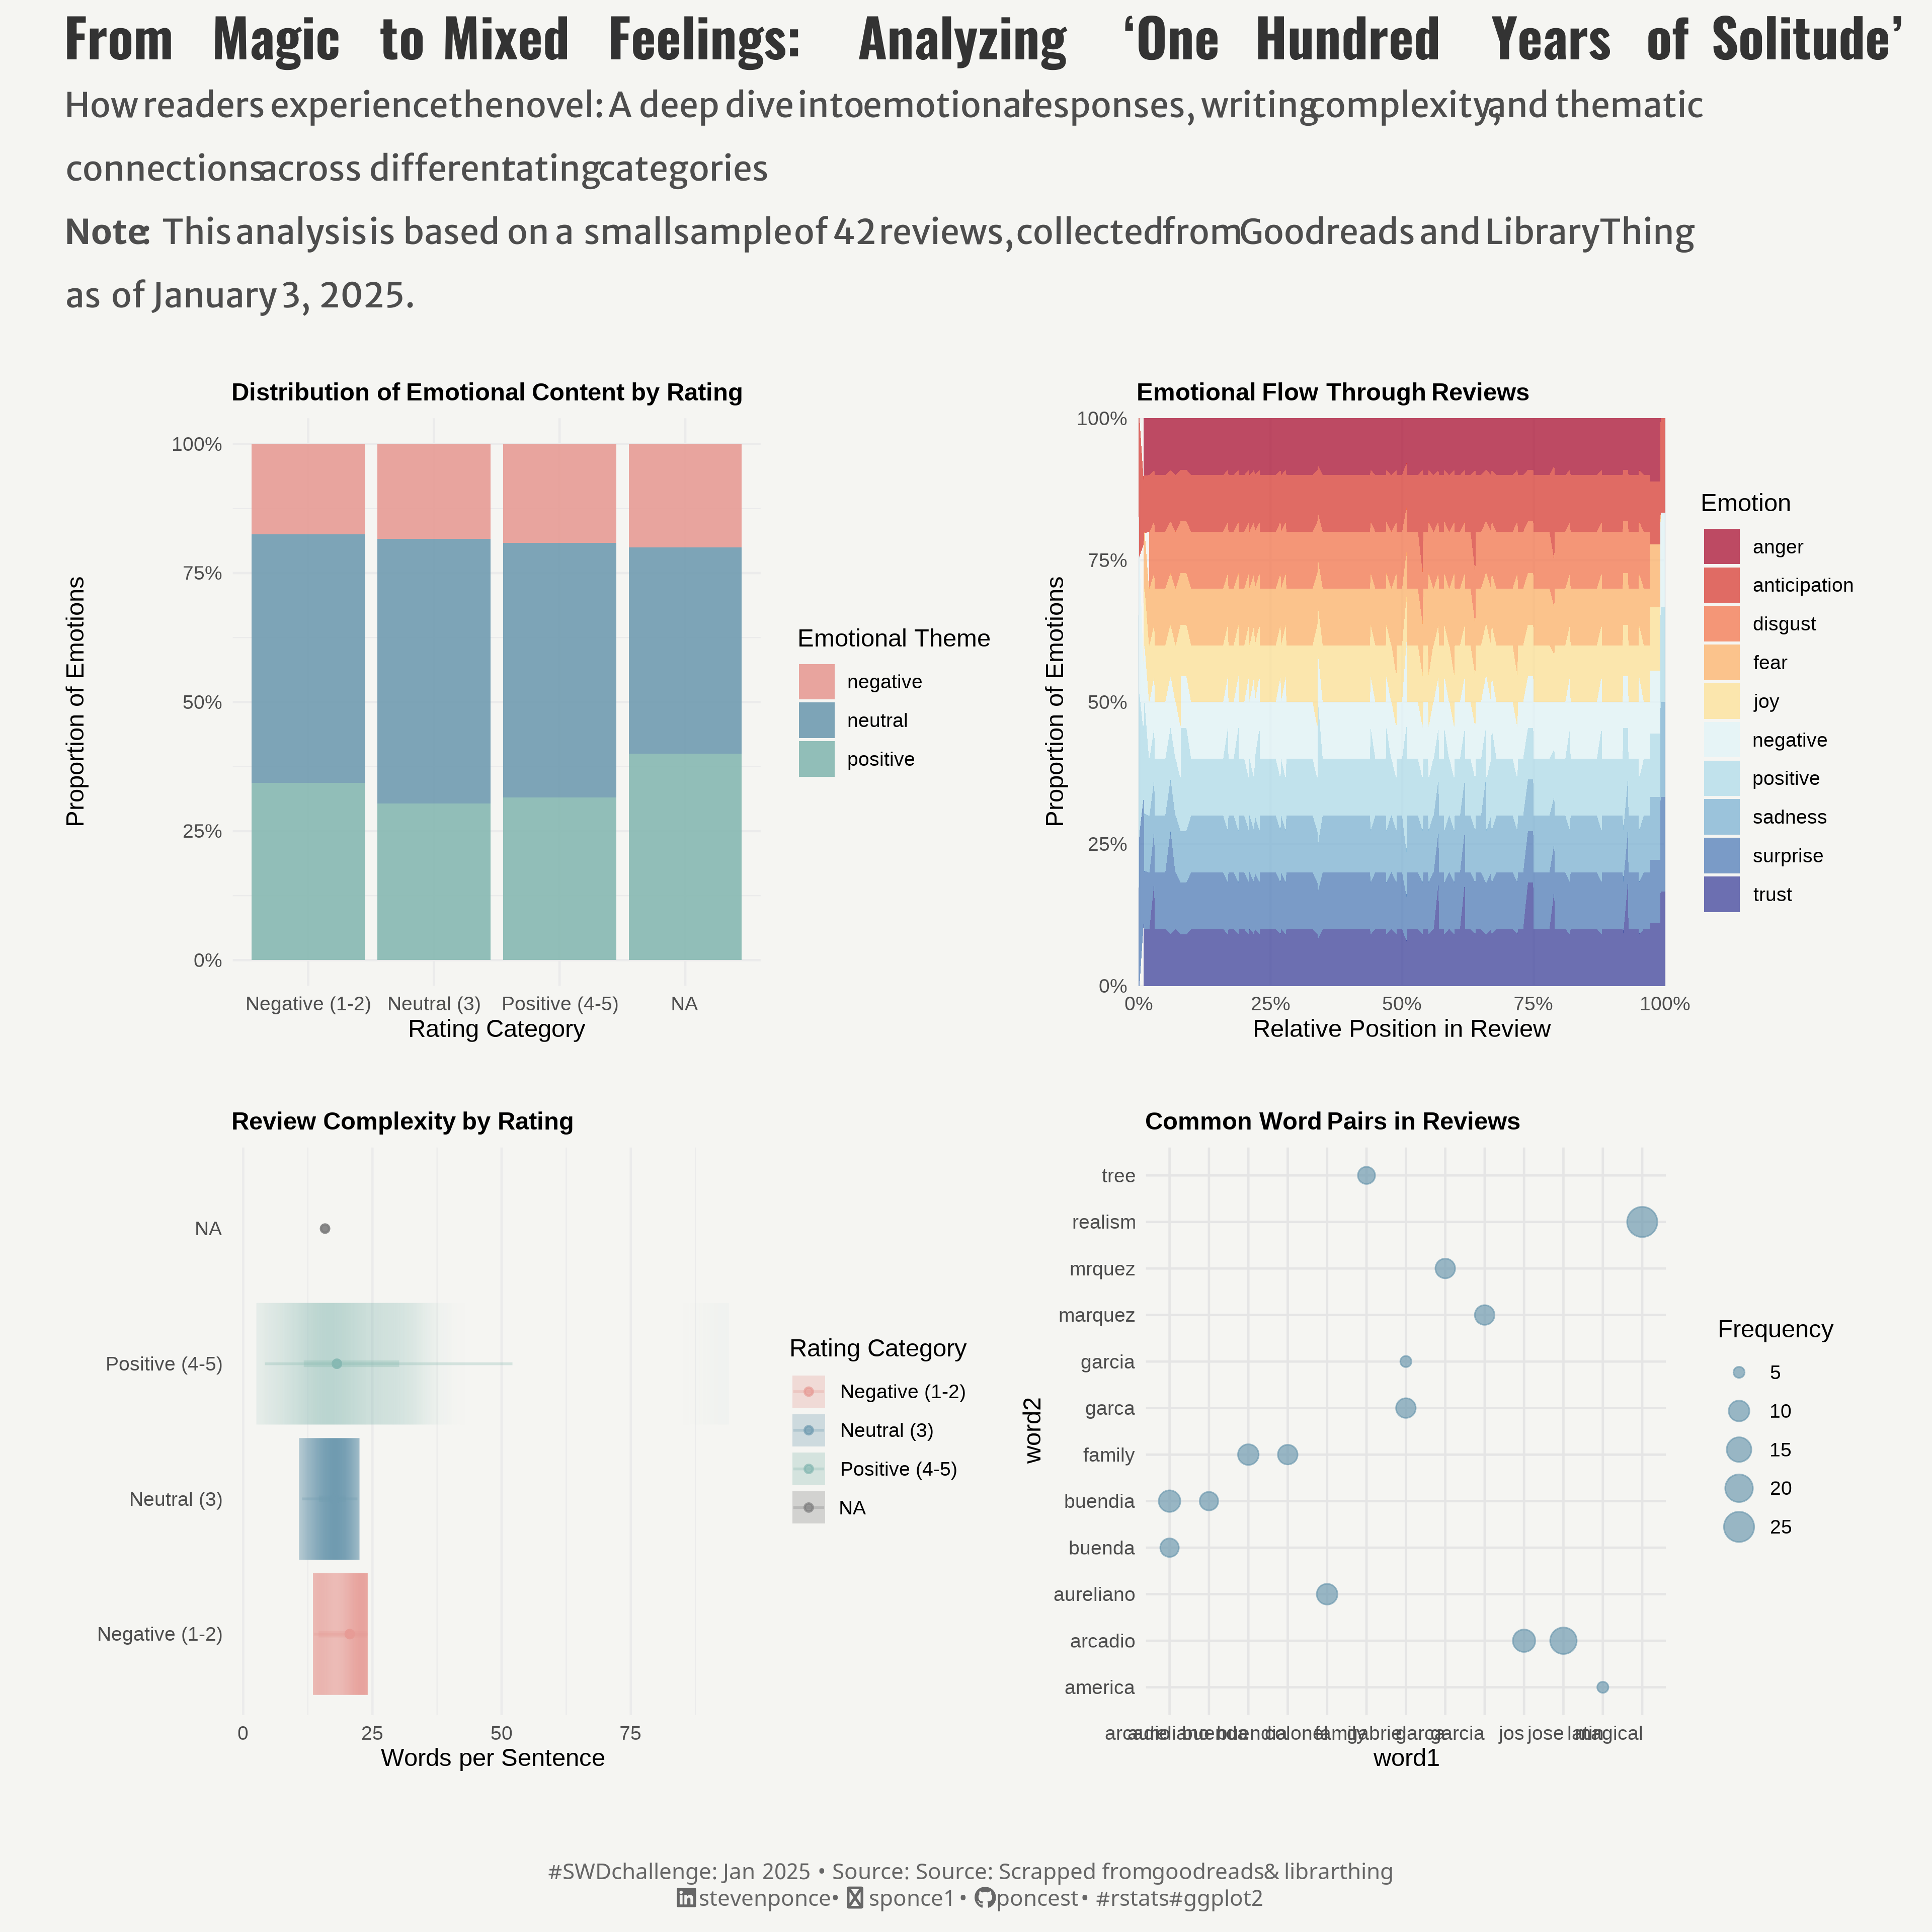{#fig-1}
**Update**: This post has been updated based on feedback from the #SWDchallenge community. The changes include:
- Fixed the chart legends that were inadvertently left out during one iteration.
### <mark> __Steps to Create this Graphic__ </mark>
#### 1. Load Packages & Setup
```{r}
#| label: load
if (!require("pacman")) install.packages("pacman")
pacman::p_load(
  tidyverse,         # Easily Install and Load the 'Tidyverse'
  ggtext,            # Improved Text Rendering Support for 'ggplot2'
  showtext,          # Using Fonts More Easily in R Graphs
  scales,            # Scale Functions for Visualization
  glue,              # Interpreted String Literals
  here,              # A Simpler Way to Find Your Files
  janitor,           # Simple Tools for Examining and Cleaning Dirty Data
  skimr,             # Compact and Flexible Summaries of Data
  camcorder,         # Record Your Plot History
  textcat,           # N-Gram Based Text Categorization
  ggdist,            # Visualizations of Distributions and Uncertainty # Visualizations of Distributions and Uncertainty # Visualizations of Distributions and Uncertainty
  tidytext,          # Text Mining using 'dplyr', 'ggplot2', and Other Tidy Tools # Text Mining using 'dplyr', 'ggplot2', and Other Tidy Tools # Text Mining using 'dplyr', 'ggplot2', and Other Tidy Tools
  patchwork          # The Composer of Plots # The Composer of Plots # The Composer of Plots
)

# Source utility functions
suppressMessages(source(here::here("R/utils/fonts.R")))
source(here::here("R/utils/social_icons.R"))
source(here::here("R/utils/image_utils.R"))
source(here::here("R/themes/base_theme.R"))
```
#### 2. Read in the Data
```{r}
#| label: read
goodreads <- read_csv(
  here::here("data/goodreads_reviews_full.csv"))

librarything <- read_csv(
  here::here("data/librarything_reviews_full.csv"))

# Combine the datasets
combined_reviews <- bind_rows(goodreads, librarything)
```
#### 3. Examine the Data
```{r}
#| label: examine
#| include: true
#| eval: true
#| results: 'hide'
#| warning: false
glimpse(goodreads)
glimpse(librarything)
glimpse(combined_reviews)
```
#### 4. Tidy Data
```{r}
#| label: tidy
combined_reviews_clean <- combined_reviews |>
  # Combine 'star_rating' and 'numeric_rating' into a single 'rating' column
  mutate(rating = coalesce(star_rating, numeric_rating)) |>
  # Convert 'review_date' to Date format
  mutate(review_date = lubridate::mdy(review_date)) |>
  # Standardize column names
  rename(
    reviewer = reviewer_name,
    date = review_date,
    text = review_text
  ) |>
  # Clean up review text
  mutate(
    text = str_squish(text), # Remove extra whitespace
    text = tolower(text),    # Convert to lowercase
    text = str_replace_all(text, "[^a-zA-Z0-9 .,!?']", "") # Remove special characters
  ) |>
  # Select and reorder columns
  select(reviewer, date, rating, text, source) |>
  # Remove duplicate rows
  distinct() |>
  mutate(
    language = textcat(text),             # Add detected language as a new column
    word_count = str_count(text, "\\S+")  # Count words in text
    ) |>
  filter(language == "english")           # Keep only English reviews


# Housekeeping
rm(goodreads, librarything, combined_reviews)


# Prepare text data for sentiment analysis
review_sentiments <- combined_reviews_clean |>
  unnest_tokens(word, text) |>
  anti_join(stop_words) |>
  inner_join(get_sentiments("nrc")) |>
  # Add rating categories for comparison
  mutate(rating_category = case_when(
    rating <= 2 ~ "Negative (1-2)",
    rating == 3 ~ "Neutral (3)",
    rating >= 4 ~ "Positive (4-5)"
  ))

# 1. Revised Complexity Analysis
complexity_analysis <- combined_reviews_clean |>
  mutate(
    sentences = str_count(text, "[.!?]+"),
    words_per_sentence = word_count / sentences,
    rating_category = factor(case_when(
      rating <= 2 ~ "Negative (1-2)",
      rating == 3 ~ "Neutral (3)",
      rating >= 4 ~ "Positive (4-5)"
    ), levels = c("Negative (1-2)", "Neutral (3)", "Positive (4-5)"))
  ) |>
  filter(is.finite(words_per_sentence))

# 2. Sentiment Flow (keeping existing structure, updating colors)
sentiment_flow <- review_sentiments |>
  mutate(
    theme = case_when(
      sentiment %in% c("joy", "trust", "anticipation") ~ "positive",
      sentiment %in% c("anger", "fear", "disgust") ~ "negative",
      TRUE ~ "neutral"
    )
  ) |>
  count(rating_category, theme) |>
  group_by(rating_category) |>
  mutate(prop = n/sum(n)) |>
  ungroup()

# 3. Temporal Pattern (keeping existing structure)
temporal_pattern <- review_sentiments |>
  group_by(reviewer) |>
  mutate(
    position = row_number(),
    position_pct = position/n()
  ) |>
  count(position_pct = round(position_pct, 2), sentiment) |>
  ungroup()

# 4. Simplified Bigram Network
bigram_graph <- combined_reviews_clean |>
  unnest_tokens(bigram, text, token = "ngrams", n = 2) |>
  separate(bigram, c("word1", "word2"), sep = " ") |>
  filter(
    !word1 %in% stop_words$word,
    !word2 %in% stop_words$word,
    !is.na(word1),
    !is.na(word2)
  ) |>
  count(word1, word2, sort = TRUE) |>
  filter(n >= 4) |>  # Increased threshold
  slice_head(n = 15)  # Take only top 15 pairs
```
#### 5. Visualization Parameters
```{r}
#| label: params
### |-  plot aesthetics ----
# Get base colors with custom palette
colors <- get_theme_colors(palette = c("negative" = "#E69B95", "neutral"  = "#709BB0", "positive" = "#86B8B1"))

### |-  titles and caption ----
title_text   <- str_glue("From Magic to Mixed Feelings: Analyzing 'One Hundred Years of Solitude' Reviews")

subtitle_text <- str_glue(
  "How readers experience the novel: A deep dive into emotional responses, writing complexity, and thematic\n
connections across different rating categories",

  "\n\n**Note**: This analysis is based on a small sample of 42 reviews, collected from Goodreads and LibraryThing\n
as of January 3, 2025.")

# Create caption
caption_text <- create_swd_caption(
  year = 2025,
  month = "Jan",
  source_text = "Source: Scrapped from goodreads & librarthing"
)


# |- fonts ----
setup_fonts()
fonts <- get_font_families()

### |-  plot theme ----
# Start with base theme
base_theme <- create_base_theme(colors)


# Add weekly-specific theme elements
weekly_theme <- extend_weekly_theme(
    base_theme,
    theme(
      plot.margin         = margin(t = 10, r = 20, b = 10, l = 20),
      axis.title.x        = element_text(margin = margin(10, 0, 0, 0), size = rel(1.1),
                                         color = colors$text, family = fonts$text, face = "bold", hjust = 0.5),
      axis.title.y        = element_text(margin = margin(0, 10, 0, 0), size = rel(1.1),
                                         color = colors$text, family = fonts$text, face = "bold", hjust = 0.5),
      axis.text           = element_text(size = rel(0.8), color = colors$text),
      axis.line.x         = element_line(color = "#252525", linewidth = .3),
      axis.ticks.x        = element_line(color = colors$text),
      axis.title          = element_text(face = "bold"),
      panel.grid.minor    = element_blank(),
      panel.grid.major    = element_blank(),
      panel.grid.major.y  = element_line(color = "grey85", linewidth = .4)
      )
)


# Set theme
theme_set(weekly_theme)
```
#### 6. Plot
```{r}
#| label: plot
# 1. Sentiment Flow Plot
p1 <- sentiment_flow |>
  ggplot(aes(x = rating_category, y = prop, fill = theme)) +
  geom_col(position = "fill", alpha = 0.9) +
  scale_fill_manual(values = colors$palette) +
  scale_y_continuous(labels = scales::percent) +
  labs(
    title = "<b>Distribution of Emotional Content by Rating</b>",
    fill = "Emotional Theme",
    x = "Rating Category",
    y = "Proportion of Emotions",
  ) +
  theme_minimal() +
  theme(
    plot.title = element_markdown(size = rel(1)),
    legend.position = "right",
    plot.margin = margin(t = 10, r = 10, b = 20, l = 10)
  )

# 2. Temporal Pattern Plot
p2 <- temporal_pattern |>
  ggplot(aes(x = position_pct, y = n, fill = sentiment)) +
  geom_area(position = "fill", alpha = 0.7) +
  scale_fill_brewer(palette = "RdYlBu") +
  scale_x_continuous(
    labels = scales::percent,
    breaks = c(0, 0.25, 0.5, 0.75, 1),
    expand = c(0, 0)
  ) +
  scale_y_continuous(
    labels = scales::percent,
    expand = c(0, 0)
  ) +
  labs(
    title = "<b>Emotional Flow Through Reviews</b>",
    x = "Relative Position in Review",
    y = "Proportion of Emotions",
    fill = "Emotion"
  ) +
  theme_minimal() +
  theme(
   plot.title = element_markdown(size = rel(1)),
    legend.position = "right",
    panel.grid.minor = element_blank(),
    plot.margin = margin(t = 10, r = 10, b = 20, l = 10)
  )

# 3. Complexity Analysis Plot
p3 <- complexity_analysis |>
  ggplot(aes(x = words_per_sentence, y = rating_category, fill = rating_category)) +
  stat_gradientinterval(
    aes(color = after_scale(fill)),
    point_size = 1.2,
    alpha = 0.3,
    point_alpha = 0.7
  ) +
  scale_fill_manual(
    values = c(
      "Negative (1-2)" = "#E69B95",
      "Neutral (3)"    = "#709BB0",
      "Positive (4-5)" = "#86B8B1"
    )
  ) +
  labs(
    title = "<b>Review Complexity by Rating</b>",
    x = "Words per Sentence",
    y = NULL,
    fill = "Rating Category"
  ) +
  theme_minimal() +
  theme(
    plot.title = element_markdown(size = rel(1)),
    legend.position = "right",
    panel.grid.major.y = element_blank(),
    plot.margin = margin(t = 10, r = 10, b = 20, l = 10)
  )

# 4. Bigram Network Plot
p4 <- bigram_graph |>
  ggplot(aes(x = word1, y = word2)) +
  geom_point(aes(size = n), color = colors$palette["neutral"], alpha = 0.7) +
  scale_size_continuous(range = c(2, 6)) +
  labs(
    title = "<b>Common Word Pairs in Reviews</b>",
    size = "Frequency"
  ) +
  theme_minimal() +
  theme(
    plot.title = element_markdown(size = rel(1)),
    legend.position = "right",
    axis.text.x = element_text(hjust = 1),
    panel.grid = element_line(color = "grey90"),
    plot.margin = margin(t = 10, r = 10, b = 20, l = 10)
  )

# Combine plots
combined_plots <- (p1 + p2) /
  (p3 + p4) +
  plot_annotation(
    title = title_text,
    subtitle = subtitle_text,
    caption = caption_text,
    theme = theme(
      plot.title = element_markdown(
        family = "title",
        face = "bold",
        size = rel(1.7),
        color = colors$title,
        margin = margin(b = 10)
      ),
      plot.subtitle = element_markdown(
        family = "subtitle",
        size = rel(1.1),
        color = colors$subtitle,
        margin = margin(b = 20),
        lineheight = 1.1
      ),
      plot.caption = element_markdown(
        family = "caption",
        size = 10,
        color = colors$caption,
        margin = margin(t = 20),
        hjust = 0.5,
        lineheight = 1.2
      )
    )
  ) &
  theme(plot.background = element_rect(fill =colors$background, color = NA))
```
#### 7. Save
```{r}
#| label: save
### |-  plot image ----

source(here::here("R/image_utils.R"))
save_plot_patchwork(combined_plots, type = 'swd', year = 2025, month = 01,
                    width = 12, height = 12)
```
#### 8. Session Info
::: {.callout-tip collapse="true"}
##### Expand for Session Info
```{r, echo = FALSE}
#| eval: true
#| warning: false
sessionInfo()
```
:::
#### 9. GitHub Repository
::: {.callout-tip collapse="true"}
##### Expand for GitHub Repo
The complete code for this analysis is available in [`swd_2025_01.qmd`](https://github.com/poncest/personal-website/tree/master/data_visualizations/SWD%20Challenge/2025/swd_2025_01.qmd).
For the full repository, [click here](https://github.com/poncest/personal-website/).
:::
#### 10. References
::: {.callout-tip collapse="true"}
##### Expand for References
The web scraping scripts used to collect the review data:
- Goodreads: [`goodreads_web_scraping.R`](https://github.com/poncest/SWDchallenge/blob/main/2025/01_Jan/goodread_web_scrapping.R)
- LibraryThing: [`librarything_web_scraping.R`](https://github.com/poncest/SWDchallenge/blob/main/2025/01_Jan/librarything_web_scrapping.R)
Data Sources:
- Goodreads: [One Hundred Years of Solitude Reviews](https://www.goodreads.com/book/show/320.One_Hundred_Years_of_Solitude)
- LibraryThing: [One Hundred Years of Solitude Reviews](https://www.librarything.com/work/5864)
:::
